OCR & Speech Workspace
A 400-page scanned PDF is where most OCR demos quietly die: one giant request, one timeout, nothing to show.
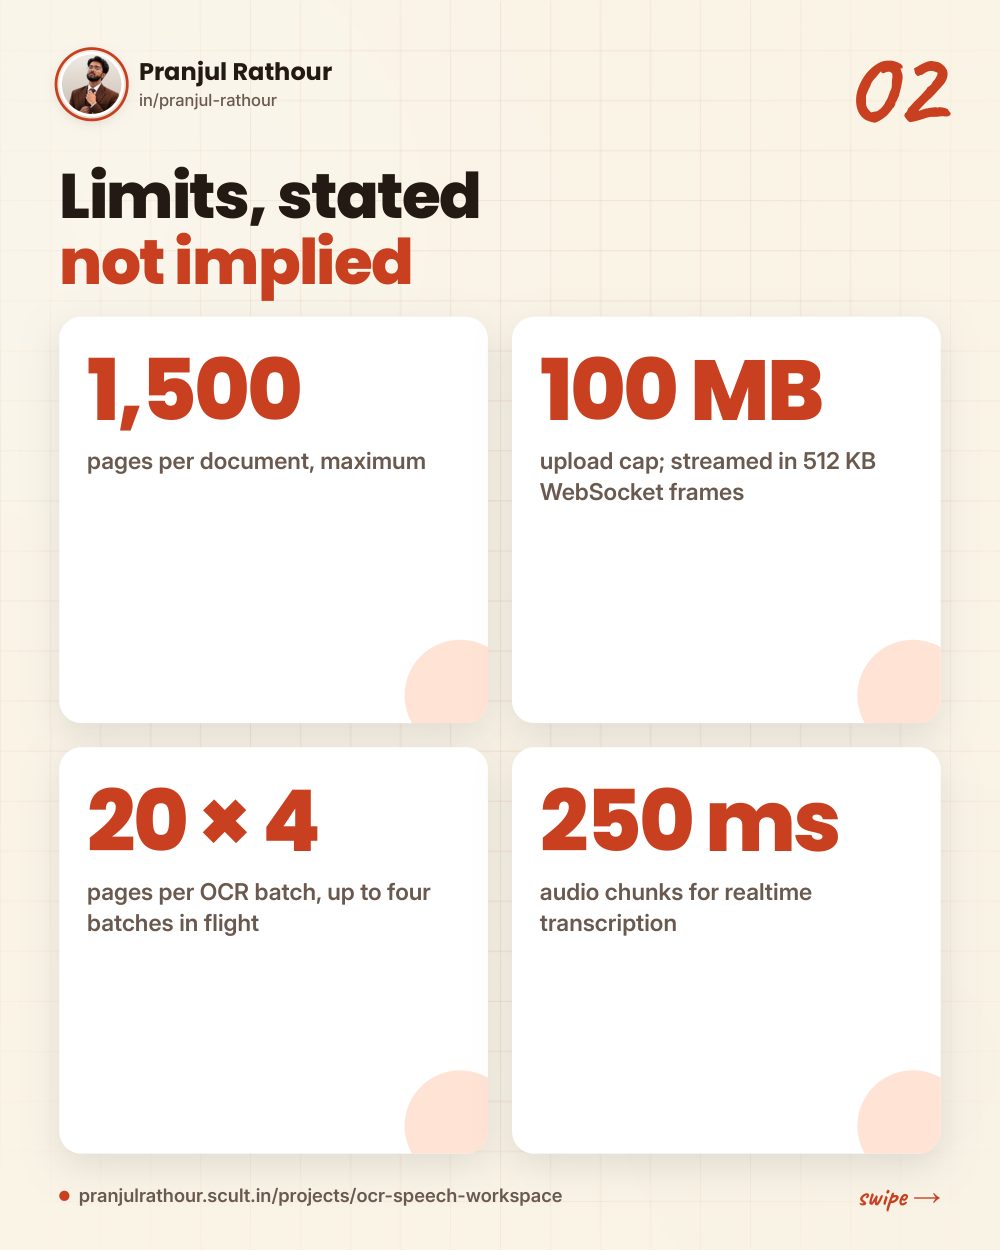
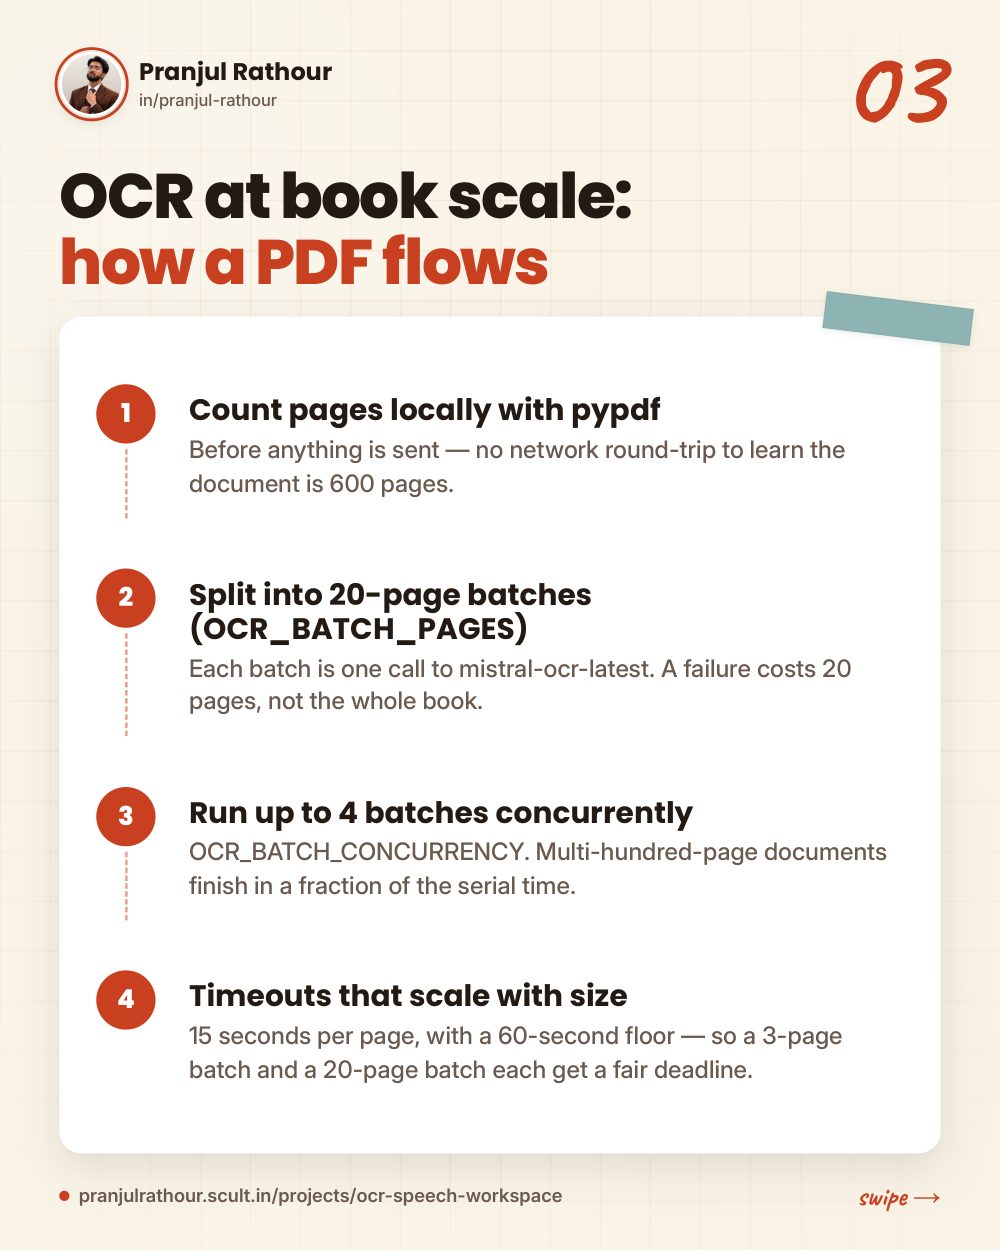
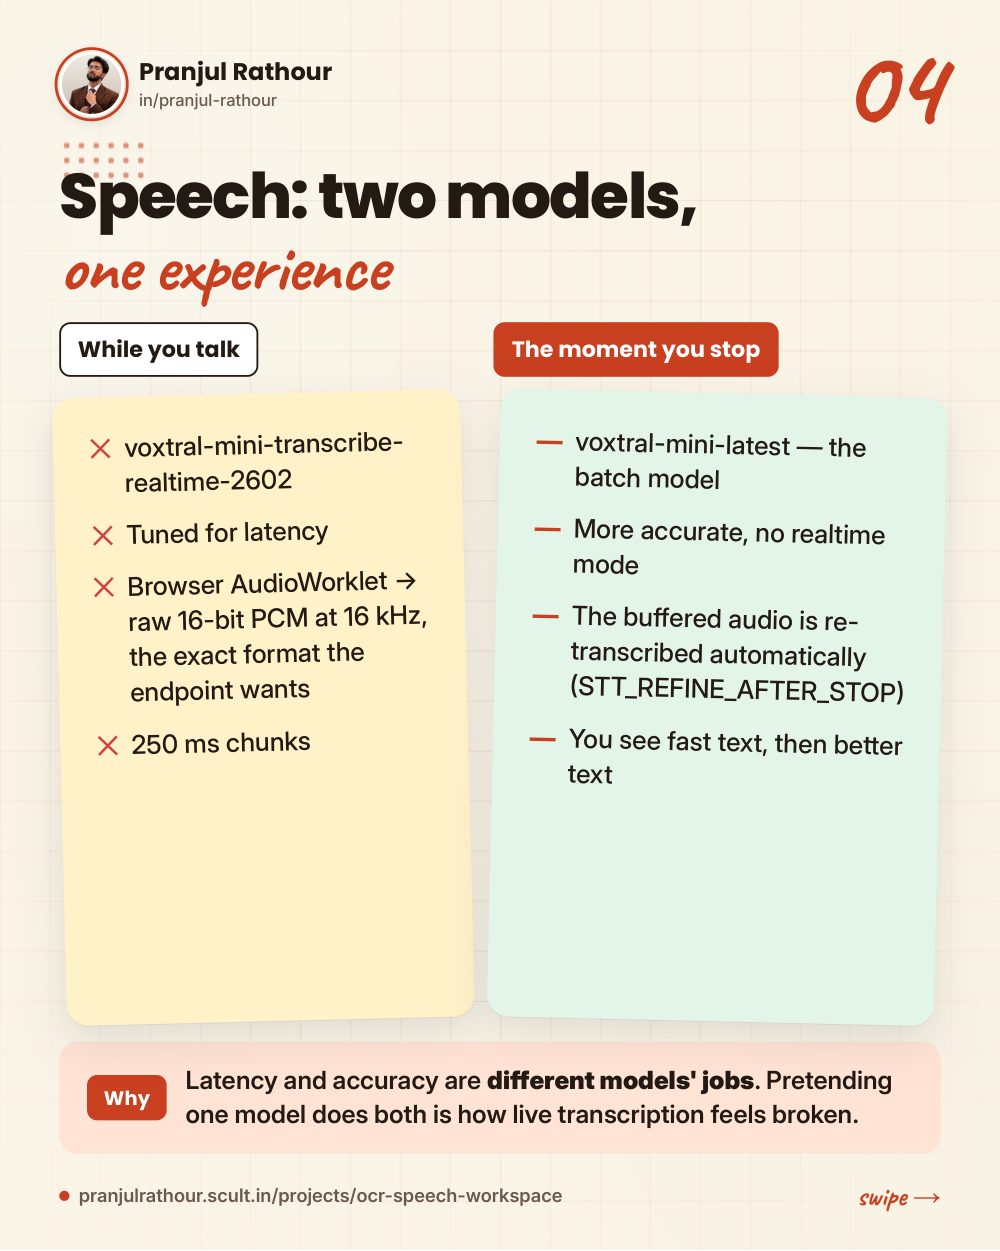
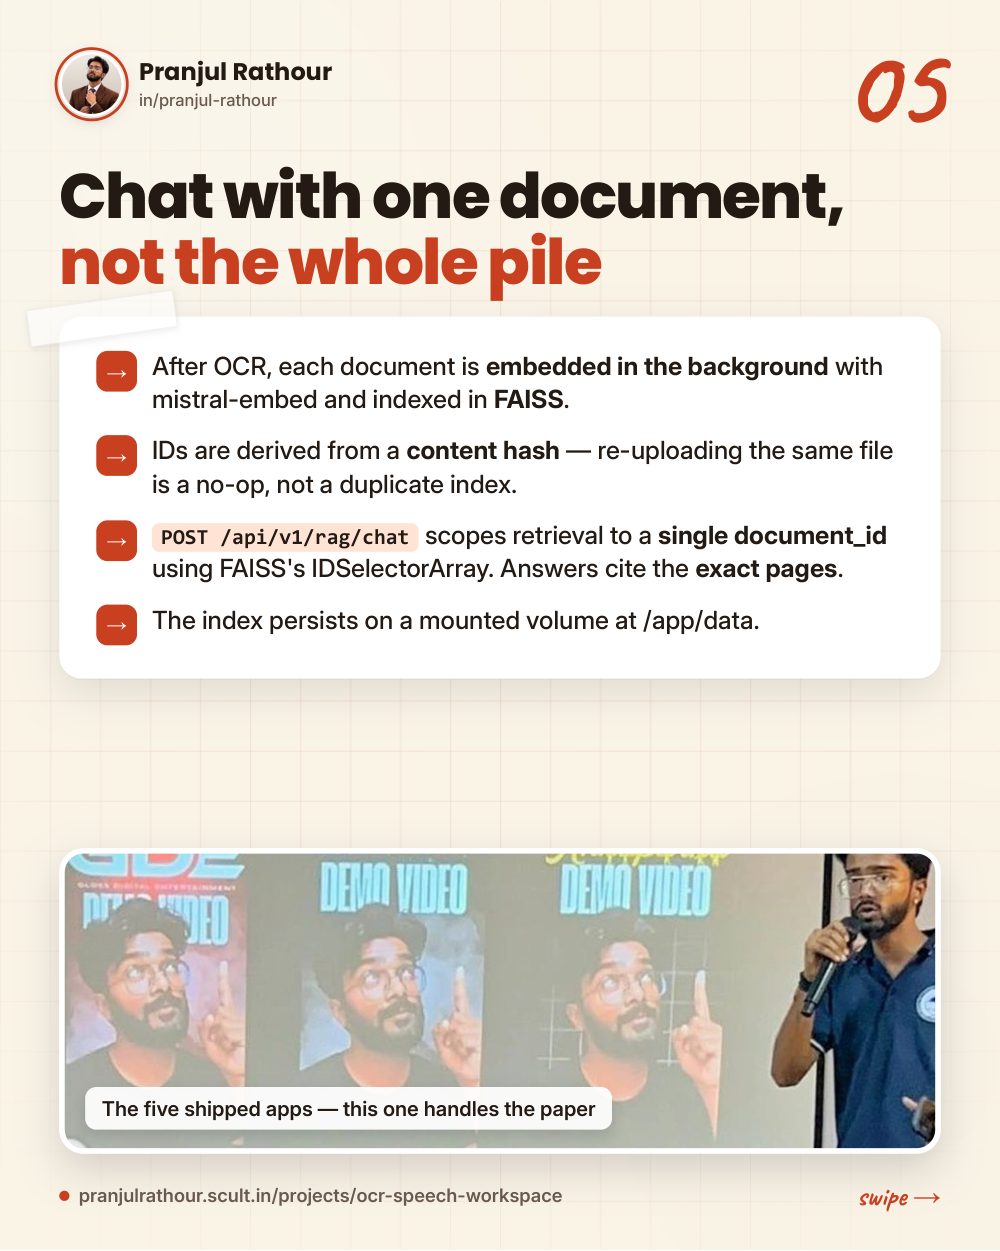
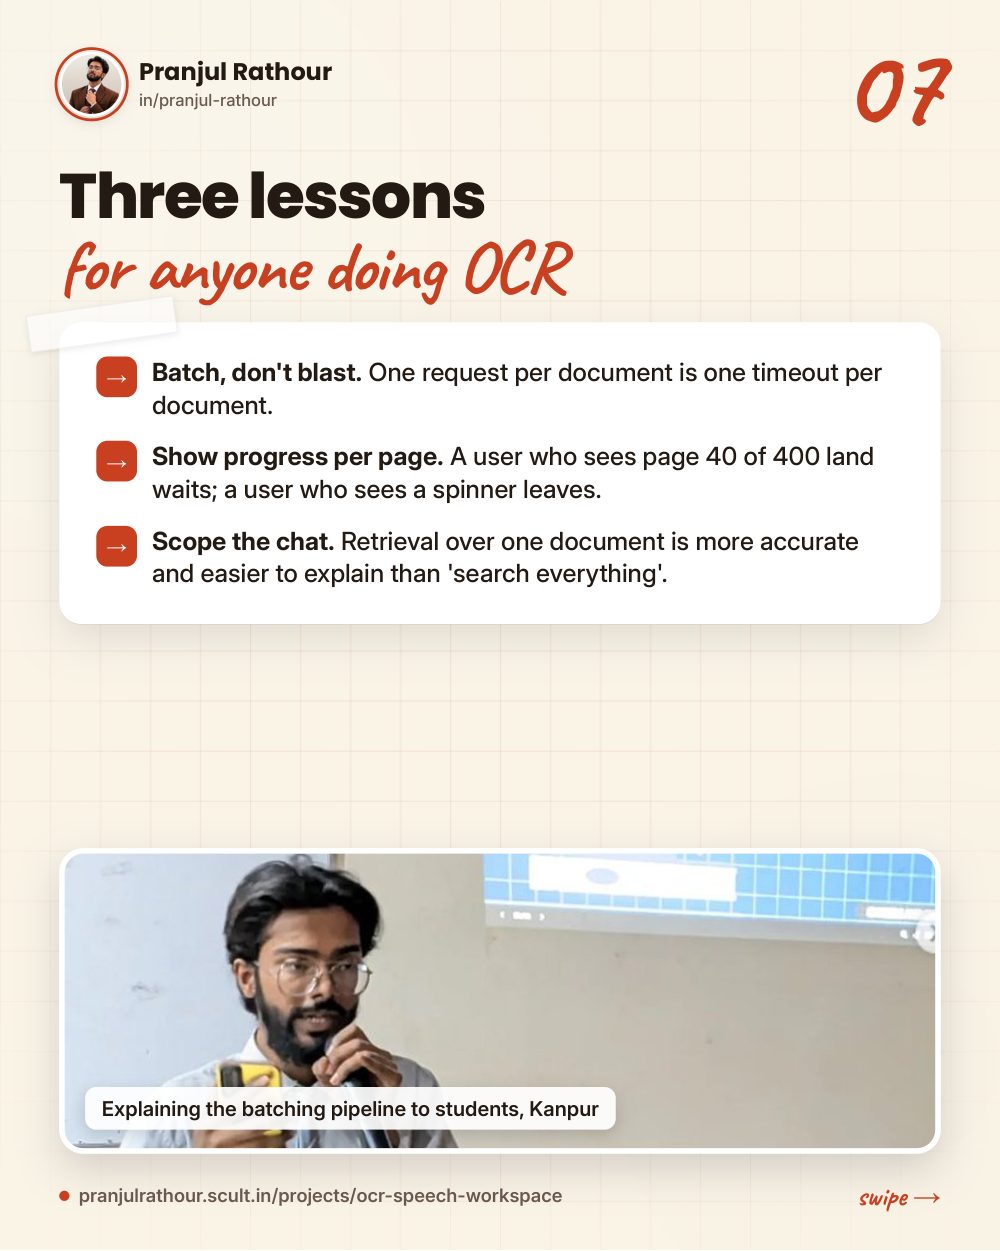
A 400-page scanned PDF is where most OCR demos quietly die: one giant request, one timeout, nothing to show. The OCR & Speech Workspace splits it into 20-page batches, runs up to four at once, and shows progress as pages land. Speech works the same way — a realtime model for latency while you talk, a more accurate batch model that re-transcribes the moment you stop. Then every document becomes a scoped knowledge base you can chat with, citing the exact page. All on Mistral's models. Here's the architecture and the numbers. Built at NextUpgrad Web Solutions. I also build tools.scult.in — 15 free tools, 1,200+ prompts and a 50,000-skill library, free for anyone, no signup.
More carousels
Want this as a live session at your college?
Open to GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges.
