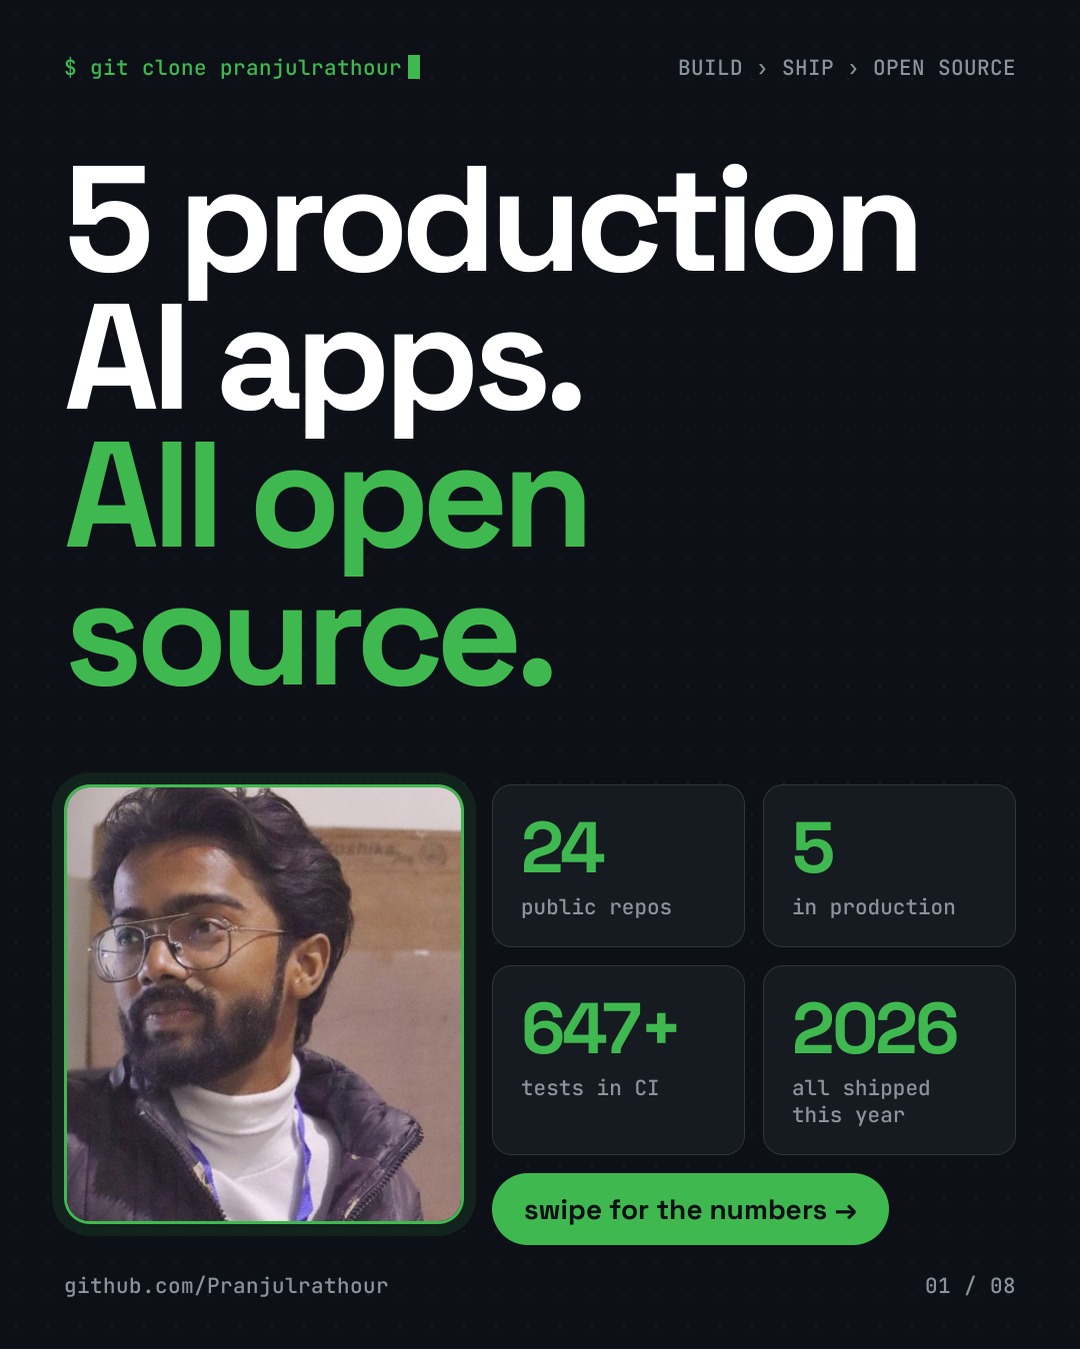
647 tests across five AI apps
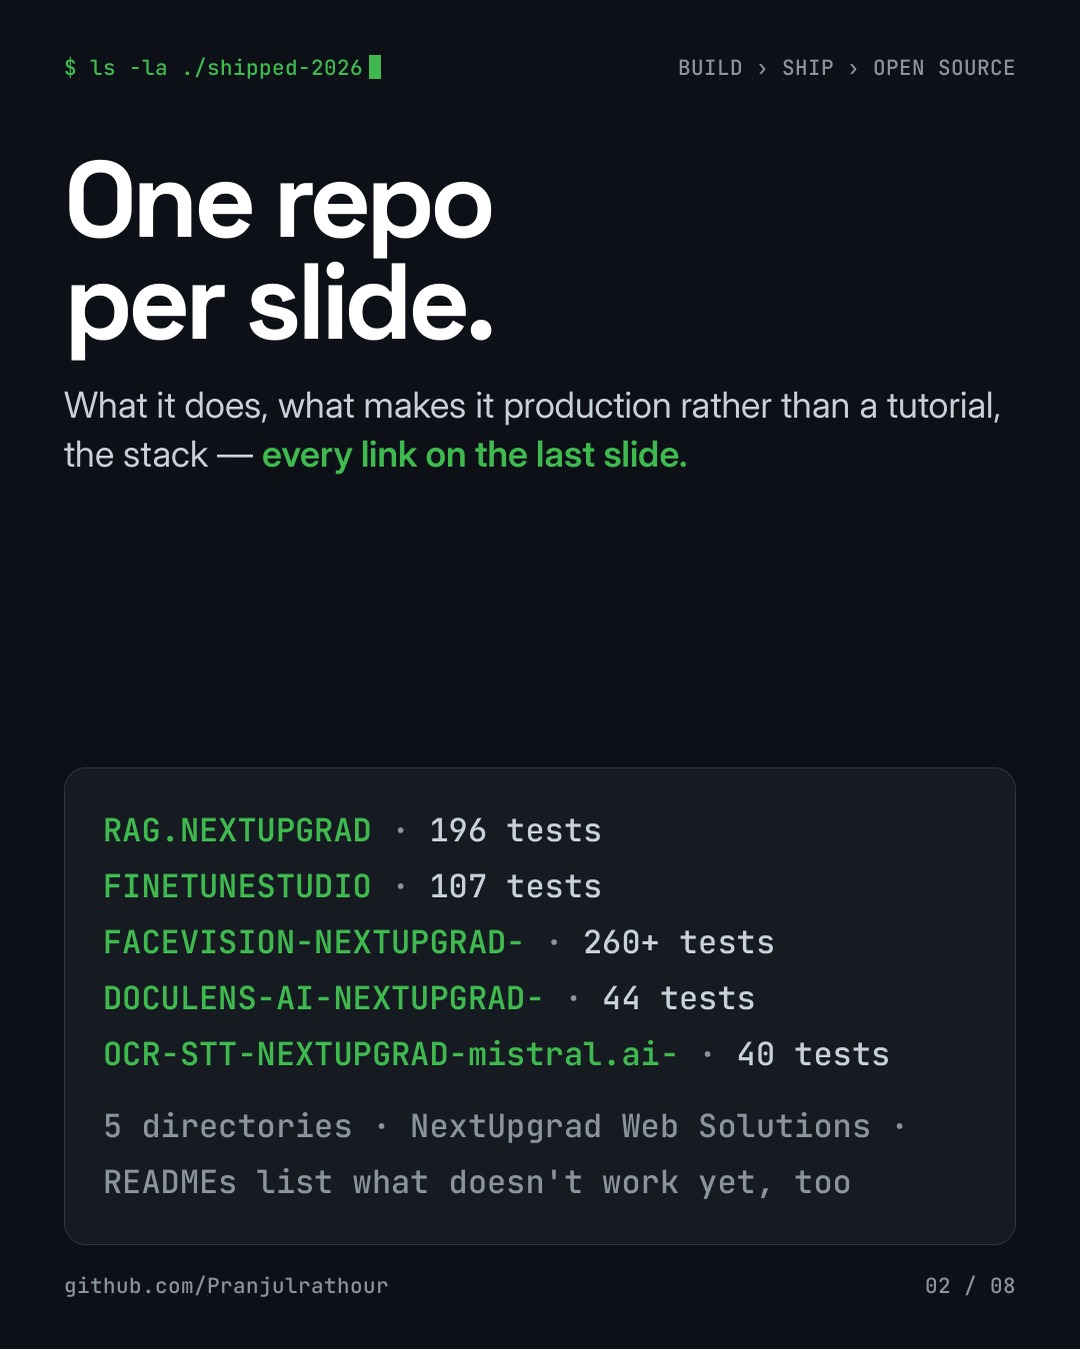
"Does it return 200" is not a test of an AI product. Across the five production apps I shipped this year the suites test the thing that can actually go wrong in each modality:
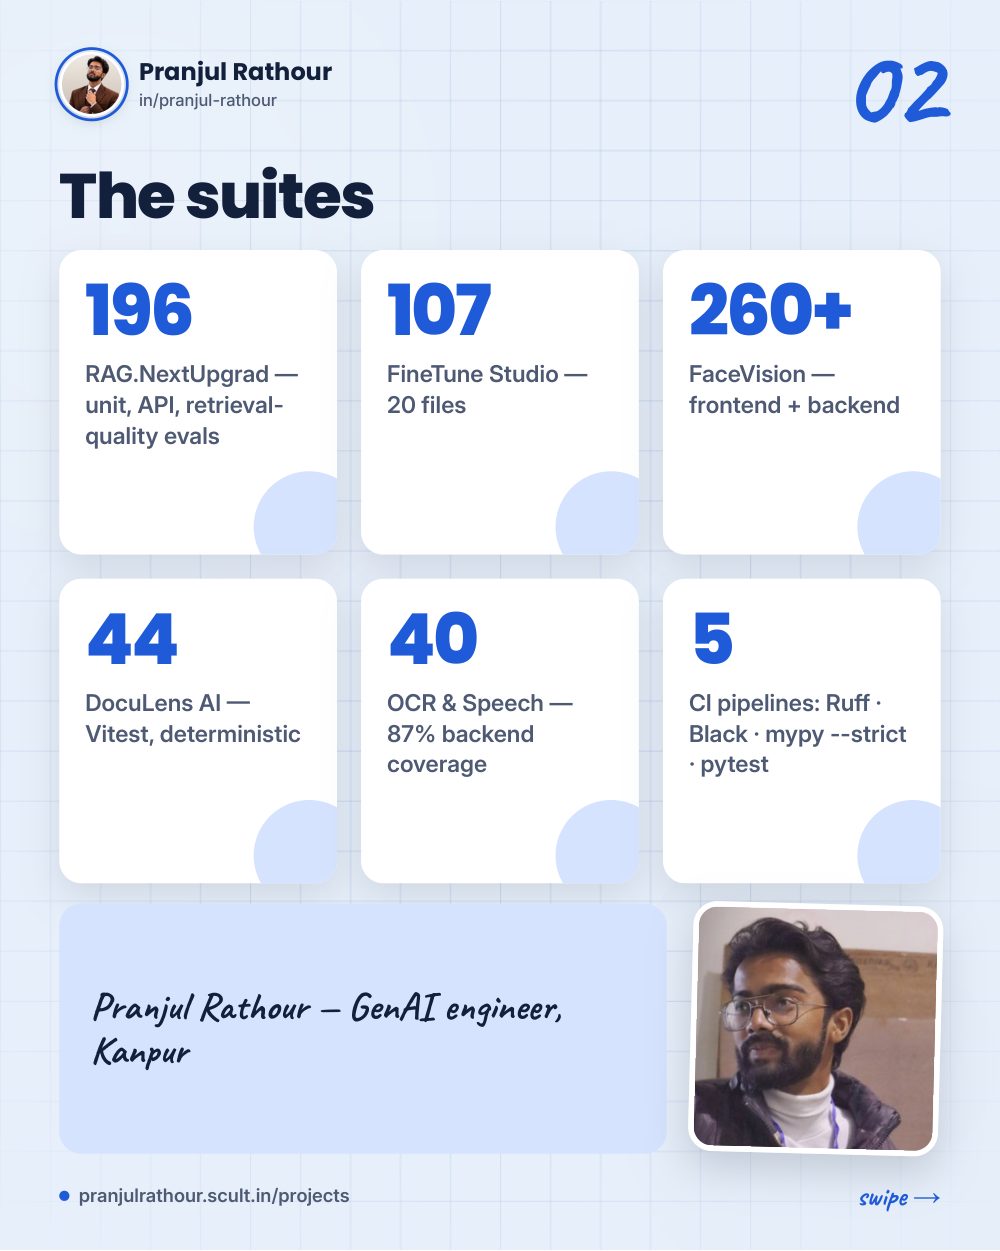
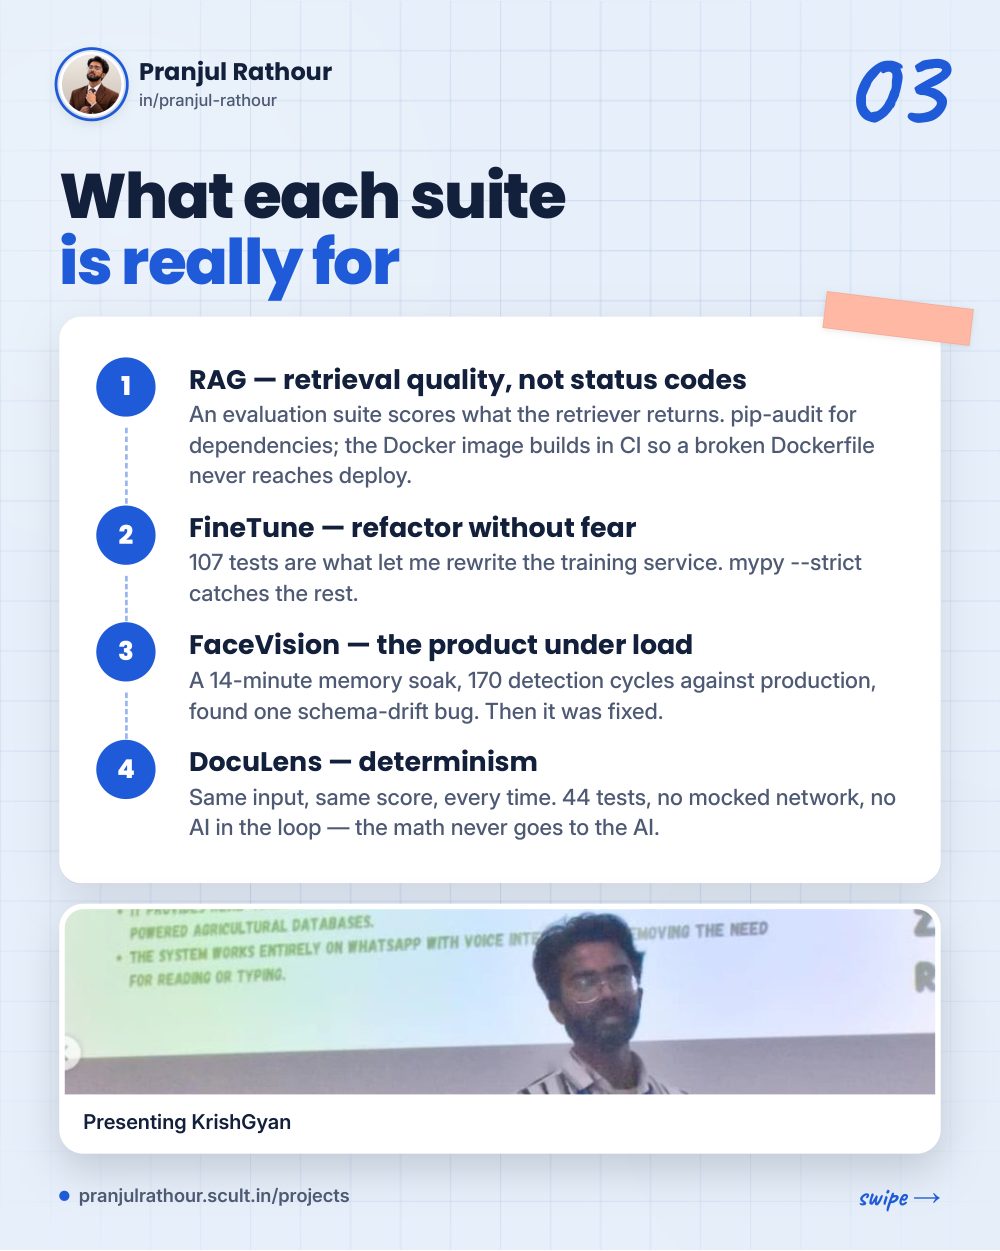
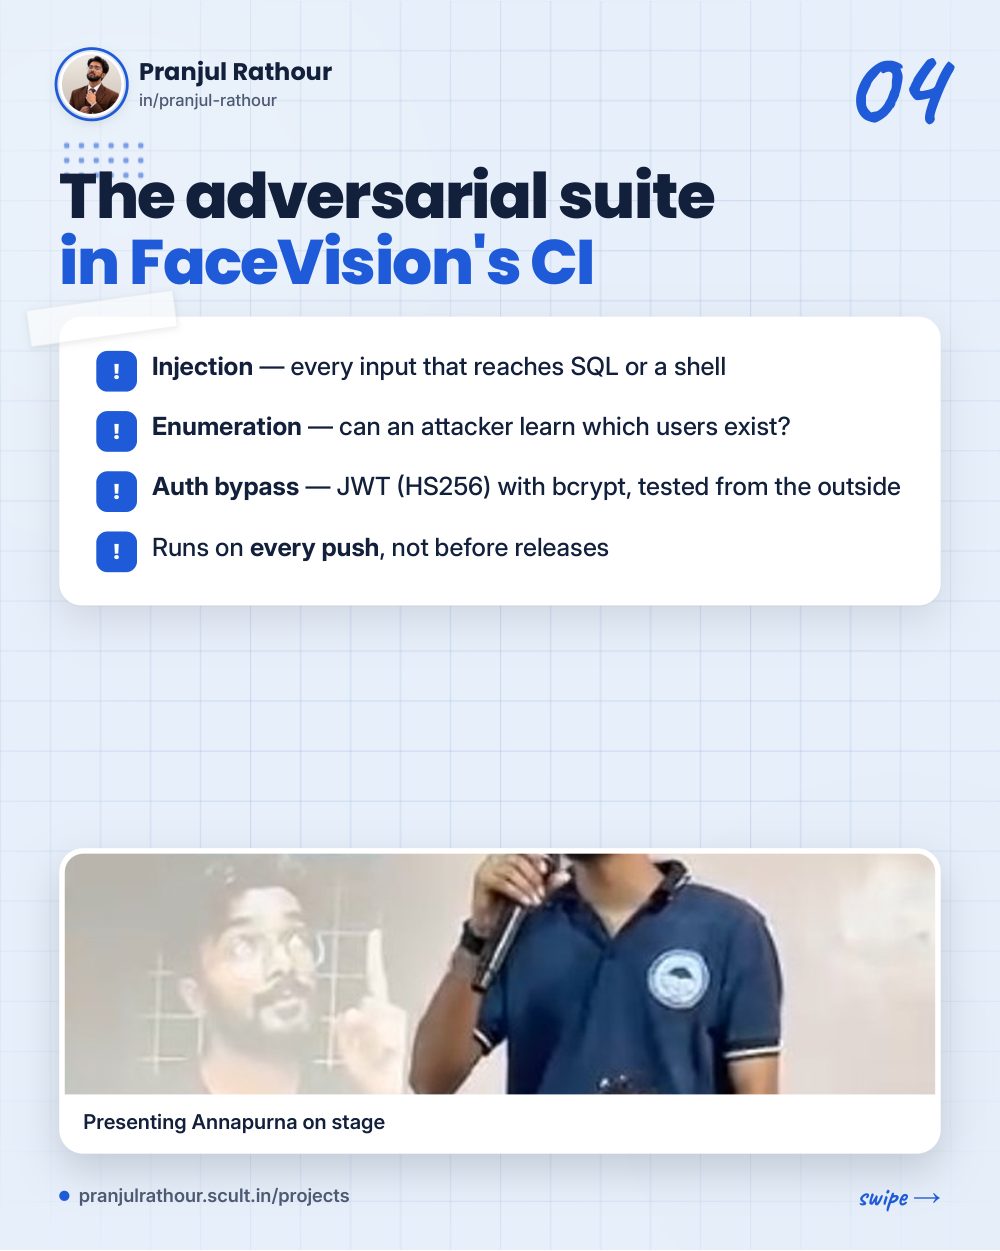
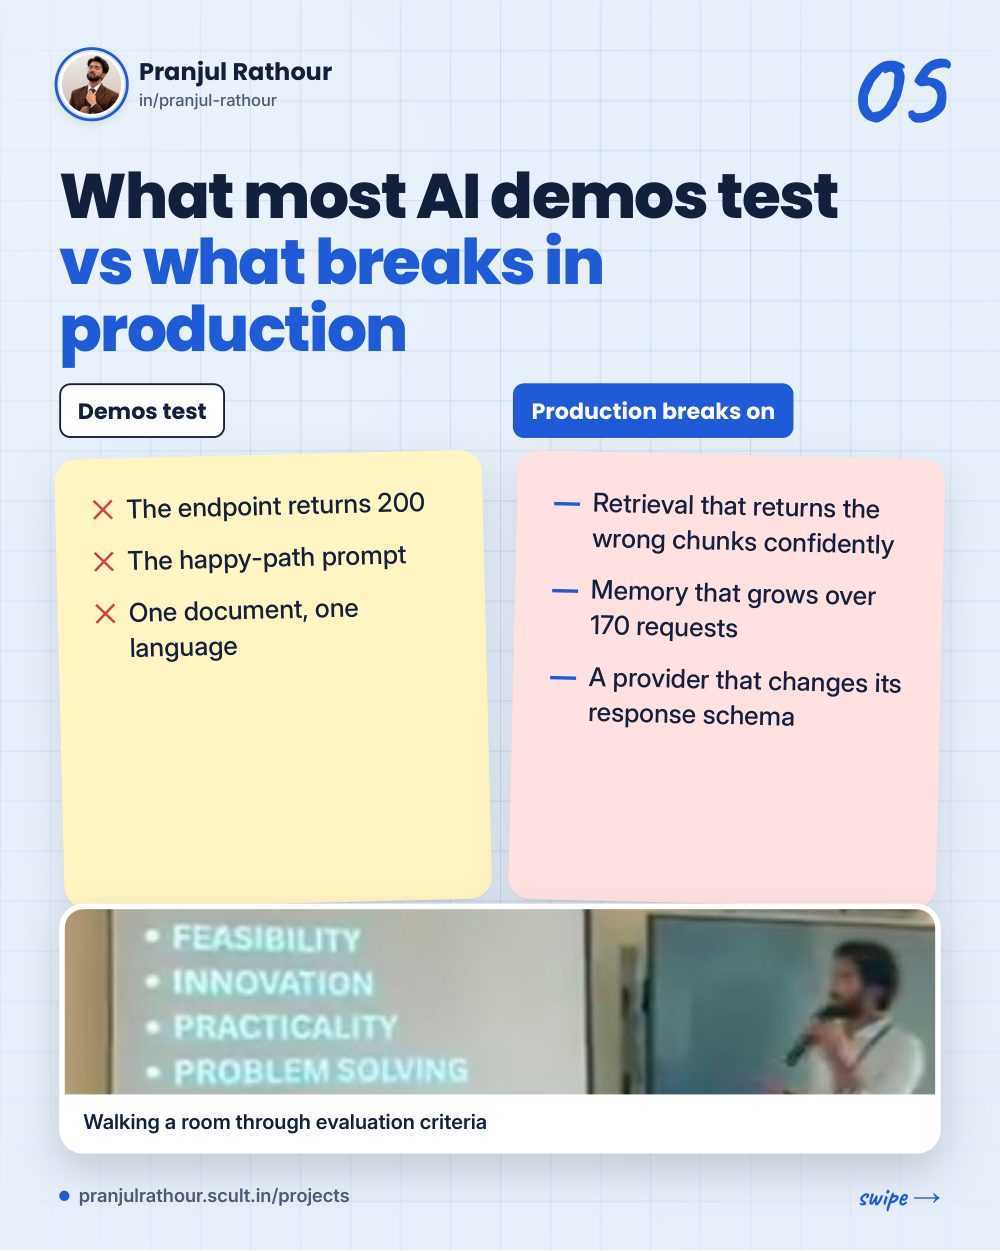
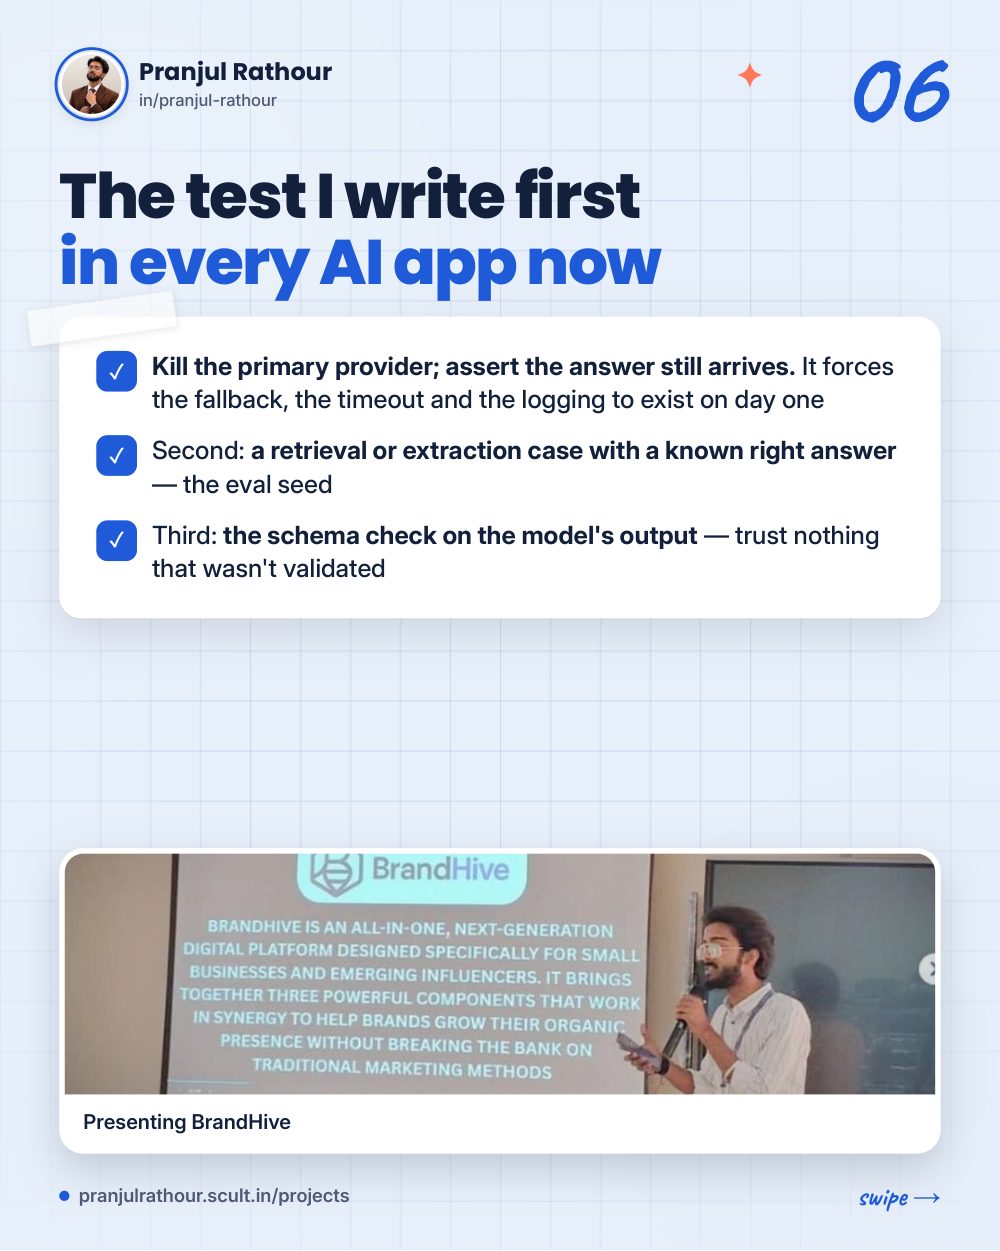
"Does it return 200" is not a test of an AI product. Across the five production apps I shipped this year the suites test the thing that can actually go wrong in each modality: RAG.NextUpgrad — 196 tests including an evaluation suite that scores retrieval quality, plus pip-audit and a Docker build in CI. FineTune Studio — 107 tests across 20 files with ruff, black and mypy --strict. FaceVision — 260+ tests, a 14-minute memory soak of 170 detection cycles against production that found a schema-drift bug, and an adversarial suite (injection, enumeration, auth bypass) in CI. DocuLens — 44 Vitest tests over the comparator, normalisation, scoring and compliance rules with no mocked network and no AI dependency. OCR & Speech — 40 tests, 87% backend coverage, services layer 89–94%. This deck is what each suite checks and why — and the one test I now write first in every AI app. I also build tools.scult.in — 15 free tools, 1,200+ prompts and a 50,000-skill library, free for anyone, no signup.
More carousels
Want this as a live session at your college?
Open to GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges.
